Firecrawl
Turns websites into LLM-ready Markdown or structured data for agents.
Website captured Oct 19
Pull the right outside knowledge into context, just in time: search, RAG, embeddings, rerankers, docs and code fetchers.
30 listed entries
Turns websites into LLM-ready Markdown or structured data for agents.
Website captured Oct 19
Converts files and Office documents to Markdown, the most token-friendly format for a context window.

Open-source RAG engine with deep document understanding and built-in agent workflows.
Website captured Oct 19

Self-hostable crawler that turns any website into clean, LLM-ready Markdown.
Website captured Oct 19
Parses PDFs, Office files and scans into clean, structured documents ready for chunking and retrieval.
Website captured Oct 19
Pulls up-to-date, version-specific library docs and code examples into a coding agent's prompt, via MCP.

Document parsing, indexing and retrieval framework that turns your data into context an agent can query.
Website captured Oct 19
Cloud-native vector database built for large-scale approximate nearest-neighbor search.
Disclosure: the operator of shipping.buzz is a Qdrant Star Ambassador. No manual overrides apply to vector databases.
Graph-plus-vector RAG that retrieves entities and relations, not just chunks (EMNLP 2025).
Website captured Oct 19

Microsoft's graph-based RAG: builds a knowledge graph and community summaries to answer whole-corpus questions.
Website captured Oct 19
Open-source vector database and search engine for semantic and hybrid retrieval at scale.
Website captured Oct 19
Disclosure: the operator of shipping.buzz is a Qdrant Star Ambassador. No manual overrides apply to vector databases.

Open-source search infrastructure for AI: embed, store and query documents for retrieval.
Website captured Oct 19
Disclosure: the operator of shipping.buzz is a Qdrant Star Ambassador. No manual overrides apply to vector databases.
Vector similarity search inside Postgres, so retrieval lives next to your app data.
Disclosure: the operator of shipping.buzz is a Qdrant Star Ambassador. No manual overrides apply to vector databases.
The standard Python library for embedding, retrieval and reranking models.
Website captured Oct 19

Open-source vector database that combines vector search with structured filtering.
Website captured Oct 19
Disclosure: the operator of shipping.buzz is a Qdrant Star Ambassador. No manual overrides apply to vector databases.

Open-source ETL that turns messy documents into clean, structured elements for RAG pipelines.
Website captured Oct 19
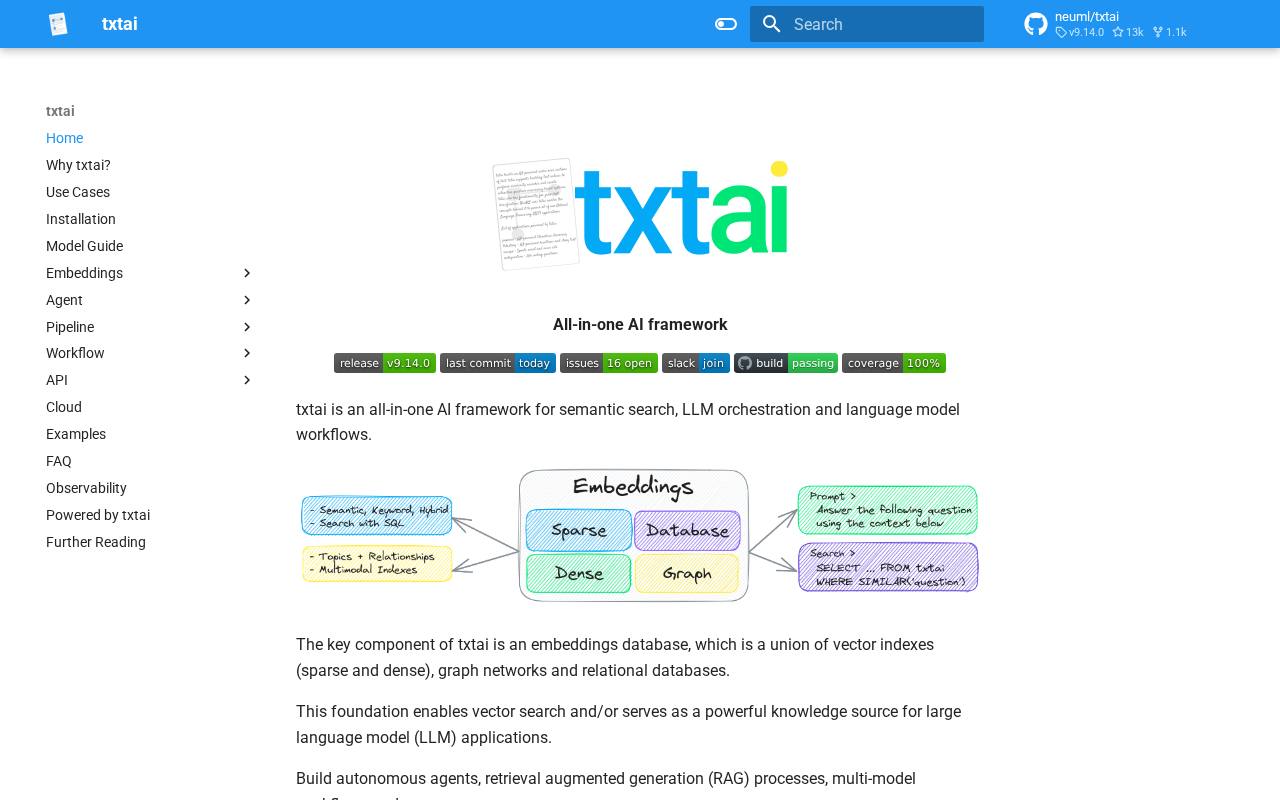

All-in-one framework for semantic search, embeddings databases and LLM workflows.
Website captured Oct 19

Embedded retrieval library for multimodal data: vector, full-text and hybrid search inside your process.
Website captured Oct 19
Disclosure: the operator of shipping.buzz is a Qdrant Star Ambassador. No manual overrides apply to vector databases.
Lightweight, fast chunking library (Python and TypeScript) for splitting text before embedding.
Website captured Oct 19
Multilingual embedding model that does dense, sparse and multi-vector retrieval in one model (BAAI).
Website captured Oct 19
Prepend chunk-specific context before embedding and BM25 indexing. Anthropic measured 49% fewer failed retrievals, and 67% fewer with reranking.
Google's 300M-parameter embedding model, small enough to run on device.
Website captured Oct 19
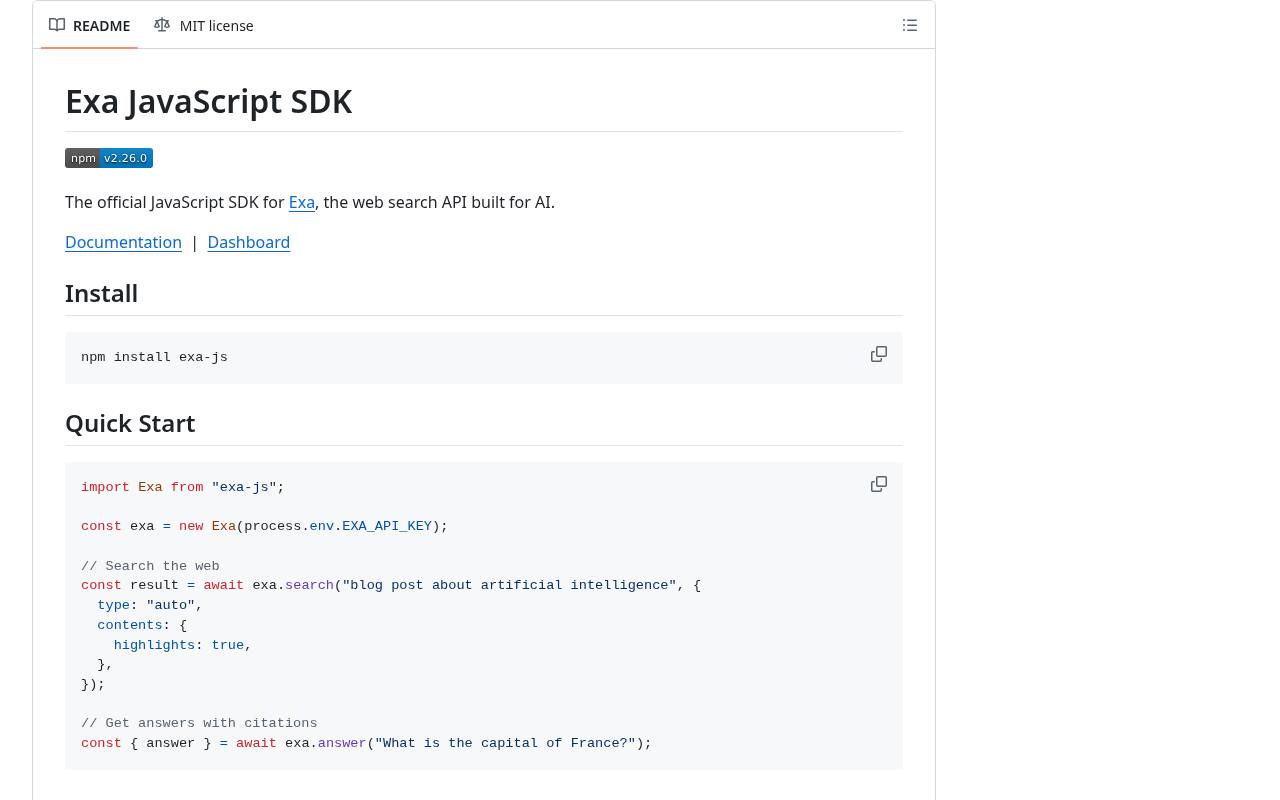
Neural web search API for agents: finds pages by meaning and returns their contents.
Website captured Oct 19
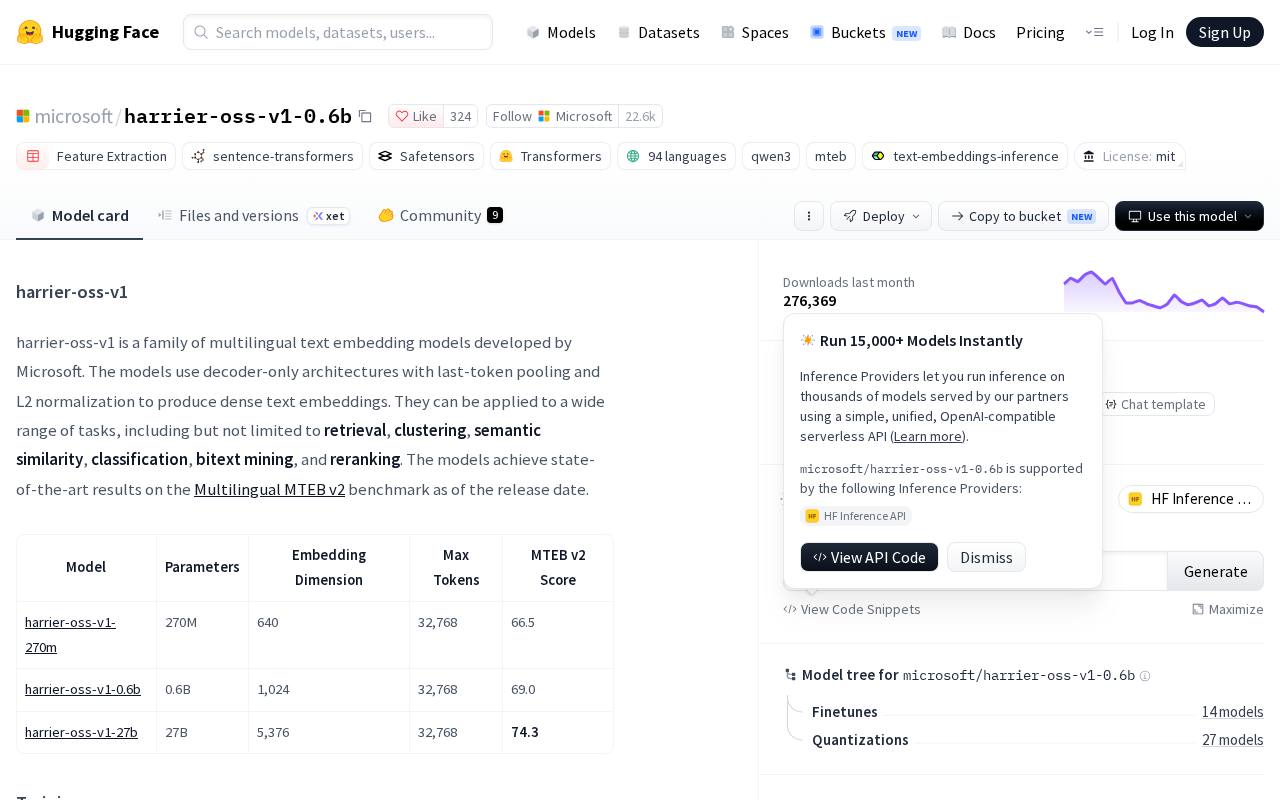
Microsoft's open 0.6B embedding model (MIT) for retrieval and semantic search.
Website captured Oct 19
Keep lightweight references (file paths, stored queries, links) in context and load the data with tools only when it's needed.
Open reranking model from Mixedbread that reorders search results before they reach the prompt.
Website captured Oct 19
Small multilingual text-embedding model from the Qwen3 family.
Website captured Oct 19
Small Qwen3 reranker: reorders retrieved passages so only the best reach the prompt.
Website captured Oct 19
Retrieve broadly (vector plus keyword), then rerank and pass only the top few chunks to the model.
Search API built for agents: returns ranked, extracted web results ready for the context window.
Website captured Oct 19